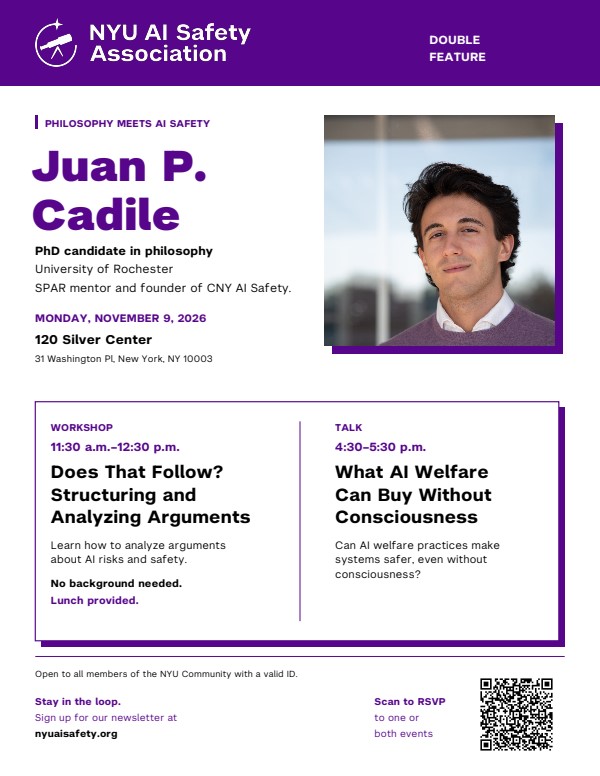
NYU AI Safety x Juan Cadile: Does That Follow? Structuring and Analyzing Arguments
- When
- Monday, November 9, 202611:30 AM – 12:30 PM ESTAdd to calendarGoogle Calendar
- Where
- Silver 120Open in Maps
- Hosted by
- NYU AI Safety Association
Reminders arrive as notifications from the NextToU iPhone app. Get the app
About
This workshop will be followed in the evening by a talk on AI Welfare. Feel free to attend one or both.
RSVP
Monday November 9th, Silver 120:
Workshop: 11:30 - 12:30, lunch provided
Talk: 4:30-5:30
WORKSHOP: Does That Follow? Structuring and Analyzing Arguments
A hands-on workshop on making arguments explicit and analyzing them. We begin with a quick toolkit: identifying a conclusion and its premises, writing an argument in standard form, distinguishing validity from soundness, spotting hidden premises and equivocations, and using the main ways of proving or refuting a claim, such as reductio ad absurdum and counterexamples. We then apply these tools to arguments from AI safety debates, such as the case that advanced AI poses catastrophic risk, or claims that interpretability results reveal what a model “knows” or “believes.” In small groups, participants reconstruct a short published argument, check whether the conclusion follows, and find the premise that does the most work with the least support. You’ll leave with a method you can reuse whenever you read or write an argument. No background in philosophy or logic is needed.
BIOGRAPHY
Juan P. Cadile is a PhD student in philosophy at the University of Rochester, working in philosophy of AI and philosophy of mind. His research asks what interpretability can and can’t tell us about AI systems and their representations. He is the author of “Detecting and Steering LLMs’ Empathy in Action” (2025). With support from a BlueDot Impact grant, he is testing whether language-model self-reports track internal states. In October 2026, he and Nick Meyer (Columbia) presented “Problems for Language Model Introspection” at NYU’s Workshop on Introspection and Self-Report in Language Models. This work separates the distinct capacities that studies call “introspection,” sets out what evidence each one requires, and shows that models fine-tuned to report injected internal states give accurate reports that are not grounded in those states. He mentors three projects in the Supervised Program for Alignment Research (SPAR), on character training, persona and emotion representations, and autonomy-preserving AI, and founded CNY AI Safety, a regional AI safety community in upstate New York.